
Jev Is Not a Chatbot: Build AI Decisions Into Your Product
Jev is not a cheaper chatbot but a structured decision engine. Use batching, confidence thresholds, and clear system boundaries to build with it.
Jev Is Not a Chatbot: Build AI Decisions Into Your Product
You have probably seen the latest AI hype around Jev, usually packaged as the promise of a 400-times cheaper coding solution. But Jev is not a cheaper LLM. If you try to use it as a chat model, you have missed what makes it cheaper: it does not write text. It makes predefined decisions that your code can use immediately.
That sounds like a limitation at first. Over the past few years, we have learned to measure AI models by how many different things they can do: answer questions, analyze information, write code, create images, and use tools as Agents.
TypeSafe AI, the company behind Jev, went in the opposite direction. Instead of building an even more general model, it removed free-form text generation and optimized the model for one shape of work: making fast, structured decisions inside software.
Jev is therefore not a new competitor to ChatGPT, Claude, or Gemini. It is closer to an intelligent if statement: useful where traditional business rules are too rigid, but a generative LLM would be too slow, expensive, or unpredictable.
You ask for a decision, not text
A traditional LLM usually returns text. Even when you ask for JSON, the model is still generating tokens sequentially. Your software then has to interpret, validate, and handle that output.
Jev offers a different contract.
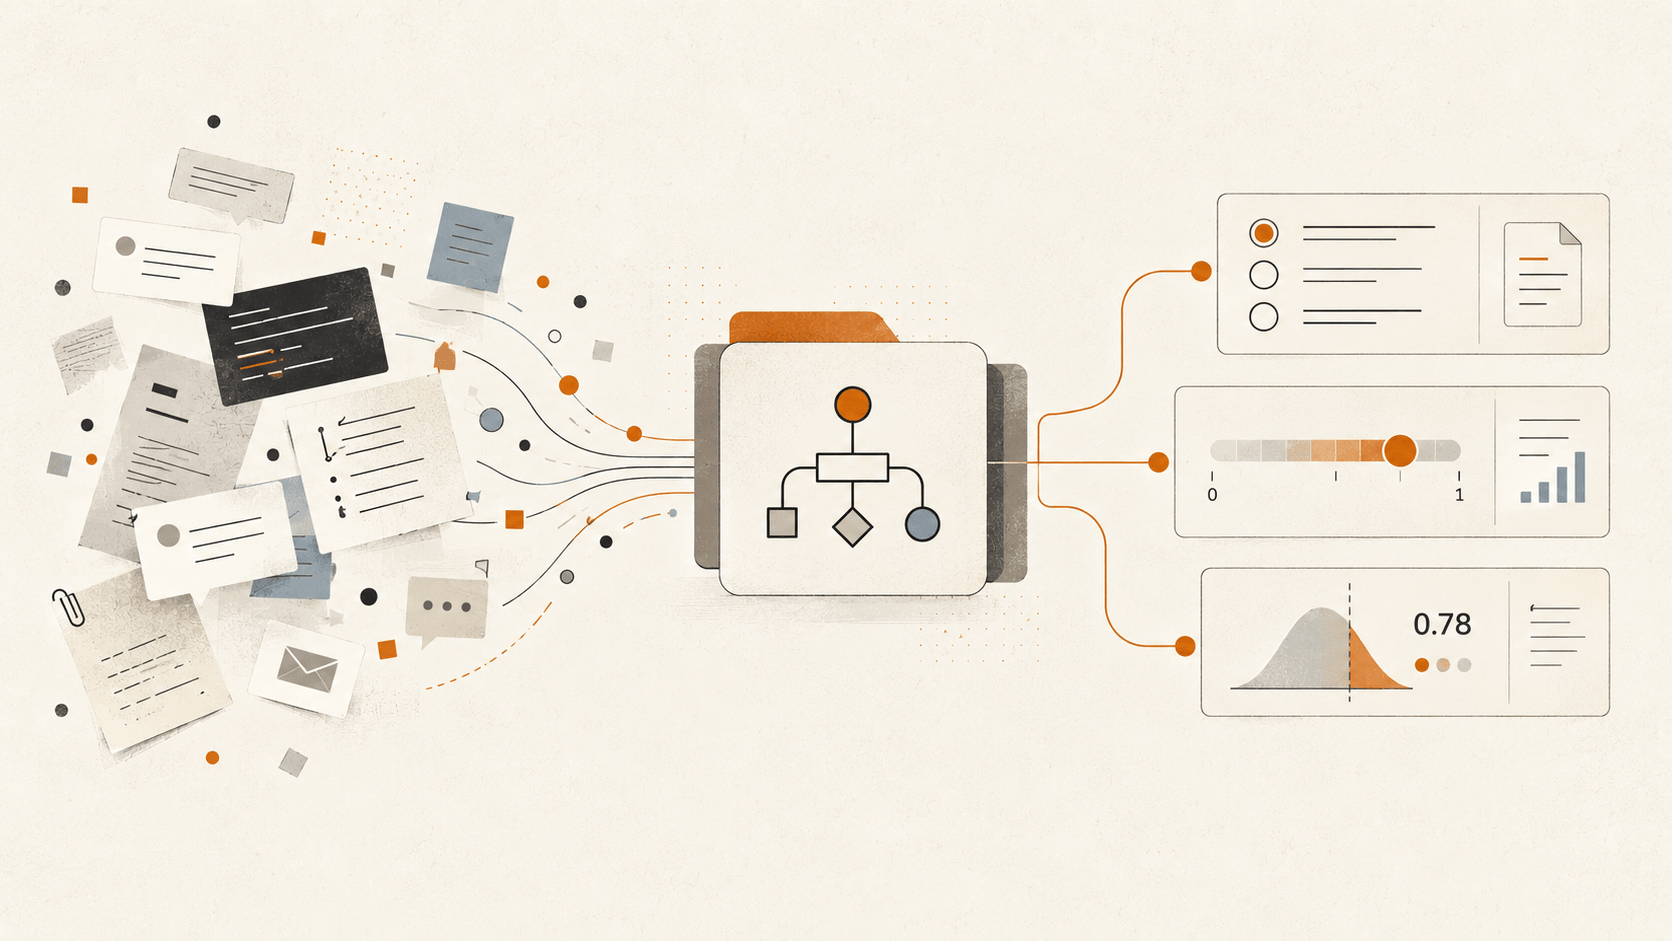
You give it the state to evaluate, such as a customer support email, a log entry, or a product record. You then define the decisions you need. The model can only return answers within the response structure you allowed in advance.
TypeSafe provides three core question types:
Choiceselects from a predefined set of options. It might classify a support ticket as a billing issue, bug report, or feature request.Scoreevaluates the state against a scale you define. It might rate the severity of a bug or the customer's level of frustration.Noulreturns a probability between 0 and 1 for whether a statement is true. It might estimate whether the customer is explicitly requesting a refund.
The response is not a polite paragraph saying, “Based on the email, this is probably a billing issue.” Your code receives a defined value and its associated probabilities directly.
That may look like a small technical difference, but it creates a completely different product logic.
A traditional LLM writes an answer for a person. Jev returns a decision intended primarily for another software component.
Architecture, not pricing, determines the real cost
Jev currently costs $0.042 per million input tokens, with no separate charge for output tokens. That is remarkably inexpensive, but the price alone does not tell you how to use the model well.
The more important detail is that Jev evaluates every question in a request in parallel against the same state.
Suppose you want to examine a support ticket across thirteen different dimensions. The wrong approach is to make thirteen API calls. You would send the same ticket thirteen times and pay for processing it thirteen times.
The better approach is a pattern TypeSafe calls speculative fan-out. You send every question you may need in one request:
- Which category does the ticket belong to?
- If it is a bug report, how severe is the issue?
- Is the customer asking for a refund?
- How frustrated does the customer appear?
- Does the case require human intervention?
- Does the message contain signs of a security risk?
It does not matter if you eventually ignore some answers. If the ticket turns out to be a feature request, your code can discard the bug severity result. Adding questions is cheap. Reprocessing the same state is wasteful.
In TypeSafe's current documentation, its own test found that batching thirteen questions was 11.5 times cheaper and 9.6 times faster than sending them separately. This is a vendor benchmark rather than an independent one, but the architectural advantage is still clear.
Jev's economics run in the opposite direction from what many teams have learned from conventional LLM APIs. You do not need to minimize the number of questions at all costs. You need to avoid repeatedly processing the shared context.
The answer is only the first decision axis
Alongside a Choice or Score result, Jev returns the full probability distribution and a confidence value between 0 and 1. The answer tells you what the model selected. Confidence tells you how clear that selection was.
This allows your product to treat model outputs differently based on uncertainty. Your code can respond to both the content of the decision and the confidence behind it:
- at high confidence, it can perform a low-risk action automatically;
- at medium confidence, it can request confirmation or gather more information;
- at low confidence, it can route the case to a person.
The threshold should not be the same for every action. Opening the wrong screen is easy to reverse. A refund, permission change, or other difficult-to-reverse operation demands much stronger certainty and separate user confirmation.
if category.confidence < 0.5:
    route_to_human(ticket)

elif category.choice == "bug_report":
    if severity.score >= 2 and severity.confidence > 0.8:
        escalate_to_engineering(ticket)
    else:
        add_to_backlog(ticket)
These numbers are starting points, not universal truths. You need to calibrate the right thresholds on your own data and match them to the consequences of a wrong decision.
Noul also works differently. A Noul value of 0.5 does not mean “medium intensity.” It means yes and no are approximately equally probable. If you need to measure intensity, use a well-defined Score scale instead.
Type safety does not guarantee a correct decision
TypeSafe says Jev cannot hallucinate, but that claim is easy to misunderstand.
Structurally, Jev cannot return a value outside the options you defined. If a Choice allows three categories, the model cannot invent and return a fourth. In that sense, malformed output and the classic form of free-text hallucination are excluded.
It can still choose the wrong category.
The type guarantee tells you that the answer has a valid shape. It does not guarantee that the decision itself is correct. You still need:
- tests using your own data;
- conservative confidence thresholds;
- a path for human review;
- verification of the actual outcome;
- and measurements of how decisions perform over time.
A confident “done” does not prove that an action actually happened. Verify the model's decision and the resulting system state separately.
★ Insight
Jev's most important lesson may not be that it eliminates hallucinations. It makes the space in which AI can fail smaller and easier to inspect.
What you should still keep out of the model
Jev's strength is also its boundary. It makes fast, closed decisions, but it is not a general-purpose problem solver.
Do not use it for:
- Free-form text generation. If you need an email, summary, or explanation, use a generative model.
- Counting and arithmetic. Let the model interpret the input and let code perform the calculation.
- Comparing dates. You can extract date components into structured values, but code should determine order and duration.
- Answering dependent questions in one round. One question cannot see another question's result. If the next decision requires new data based on an earlier answer, you need a second request.
- Processing an oversized, noisy state. More context is not automatically better. Details unrelated to the questions can reduce accuracy.
- Verifying workflow execution. Jev can decide which route to take, but your code must confirm that the action completed successfully.
The common pattern is simple: if traditional code can solve something reliably, do not hand it to the model. Jev is useful where you need human-like judgment but can define the possible outputs in advance.
Where does Jev actually fit?
Jev is not right for every product. It becomes useful when you need to make large numbers of repetitive, well-bounded decisions.
Examples include:
- categorizing and routing support tickets;
- classifying incoming documents;
- scoring signs of fraud or security risk;
- providing a first decision layer for content moderation;
- prioritizing leads, applications, or requests;
- routing between Agents and tools;
- evaluating the outputs of generative models;
- powering real-time interfaces where waiting several seconds for a model would create poor UX.
It is a weaker choice when the work requires open-ended research, creative writing, extended reasoning, or complex planning.
The right question is therefore not “Can I replace my current LLM with Jev?” It is:
Does my product contain a recurring judgment that we currently handle with rigid rules, expensive LLM calls, or continuous human review?
If the answer is yes, Jev may have a place there.
A practical pattern for integrating Jev
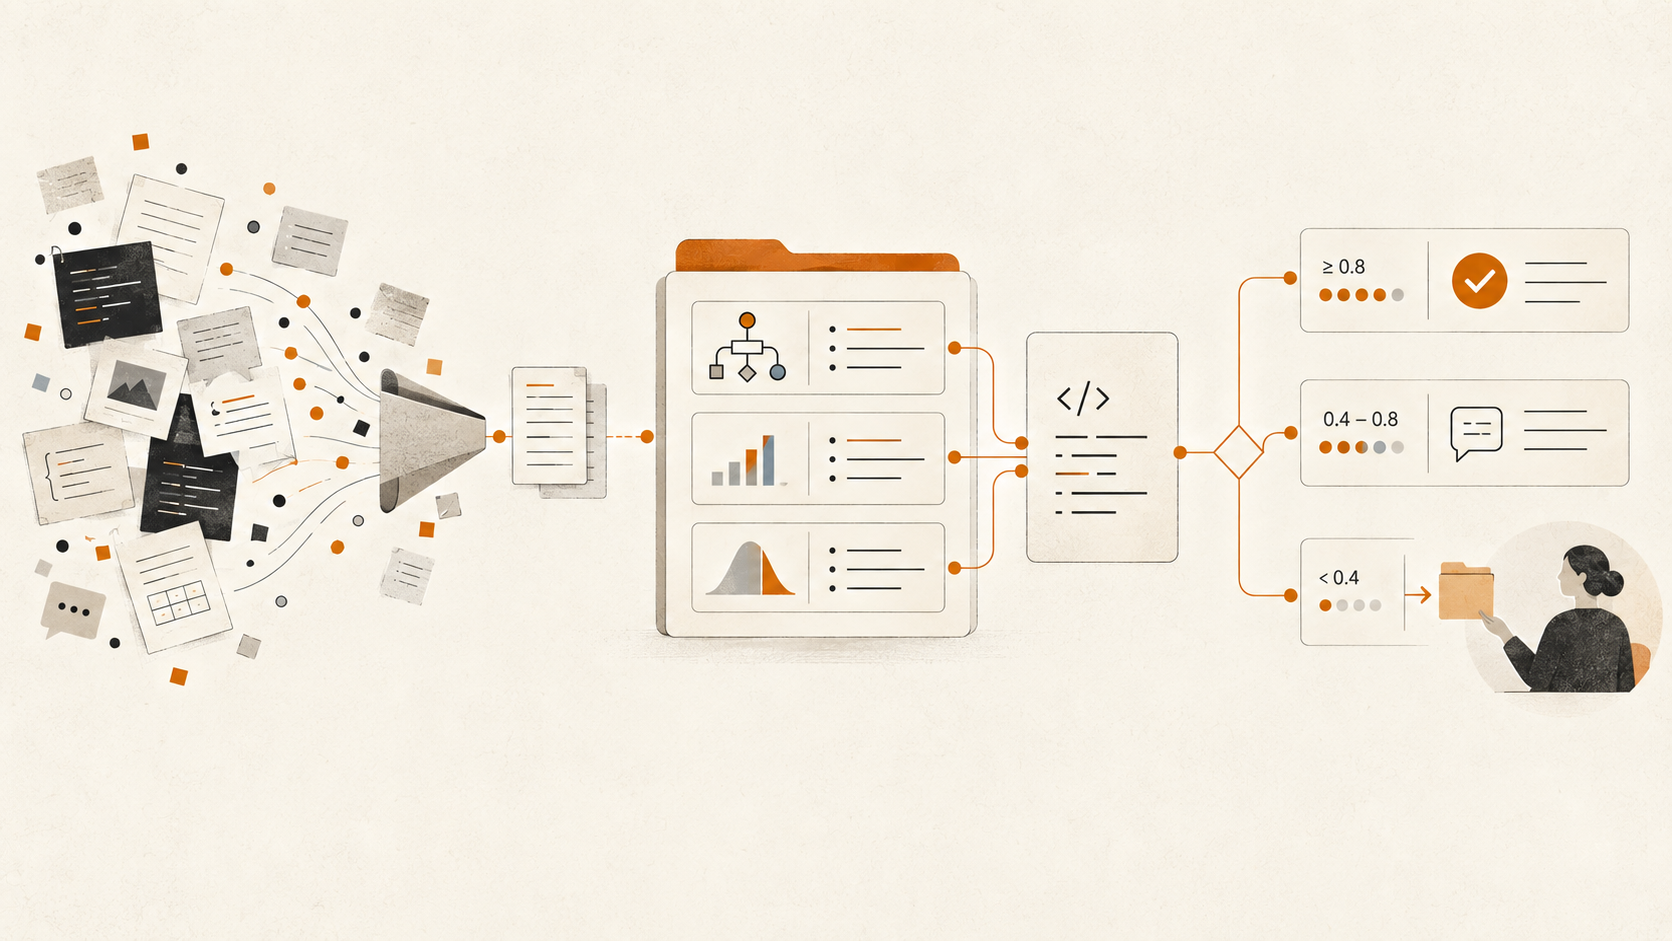
You can build a robust implementation in six steps:
- Filter the input. Send only the state that your questions genuinely need.
- Decompose complex decisions. Replace one large, vague question with several atomic Choice, Score, or Noul questions.
- Batch questions that share the same state. Include speculative questions in the first request.
- Combine answers in code. Keep calculations, weights, and business rules deterministic.
- Match confidence thresholds to risk. Use a human or deterministic fallback when confidence is low.
- Pin and log the model version. Do not assume that thresholds tuned against a moving
latestalias will remain valid.
This pattern is less spectacular than a demo of an AI Agent that appears to do everything. It is much closer to what a production product actually needs:
- narrow responsibilities;
- measurable uncertainty;
- reversible decisions and verifiable system state.
Jev's real message
The hype around Jev will naturally focus on its price and speed. But its more important advantage is the recognition that not every AI task needs a model capable of free-form generation. More reliable automation often comes from a narrower decision space, better system boundaries, and explicit risk management rather than greater general intelligence.
Jev does not replace LLMs. It adds a new layer beside them.
A generative model can research, write, or plan. Jev can quickly evaluate, classify, and choose a route. Traditional code still calculates, validates, executes, and verifies the result.
Together, these three layers can create a much more controllable AI product than the assumption that one model should understand and execute everything.
That is why Jev is interesting for more than its price. It forces us to ask the more important question again: which decisions should we delegate to AI, and which should remain in code?
Sources
More writing from the archive
Stop Micromanaging AI Agents: OpenAI Symphony
OpenAI Symphony shows how Linear and ticket based workflows can become the control plane for AI coding agents.
9 Months of Customizing Claude Code: What I Built and Why
How I turned Claude Code from a default AI assistant into a personalized workflow — 9 skills, 55 plugins, daily routines, and the philosophy behind it all.
Projects connected to this thinking
Open Brain: Building a Personal Knowledge Backend with AI
Open Brain: Building a Personal Knowledge Backend with AI What if your notes could think? Not in a sci fi way — but in a practical, "I wrote something three months ago th…
Raiffeisen Bank: End-to-End Online Account Opening
Raiffeisen Bank: End to End Online Account Opening When Raiffeisen Bank decided to let customers open a bank account entirely online — no branch visit required — they kne…